Applied AI research
Custom models, honest evaluation and a method that survives production.
Most AI demos win on cherry-picked examples and fall apart on your data. We do applied research against your specific problem — build and fine-tune the model, benchmark it against a real baseline, take the promising method from a paper into production, and tell you plainly whether it actually beats what you have today.
01 / What it gives you
Custom model development and fine-tuning on your own data and task — not a generic model bent to roughly fit.
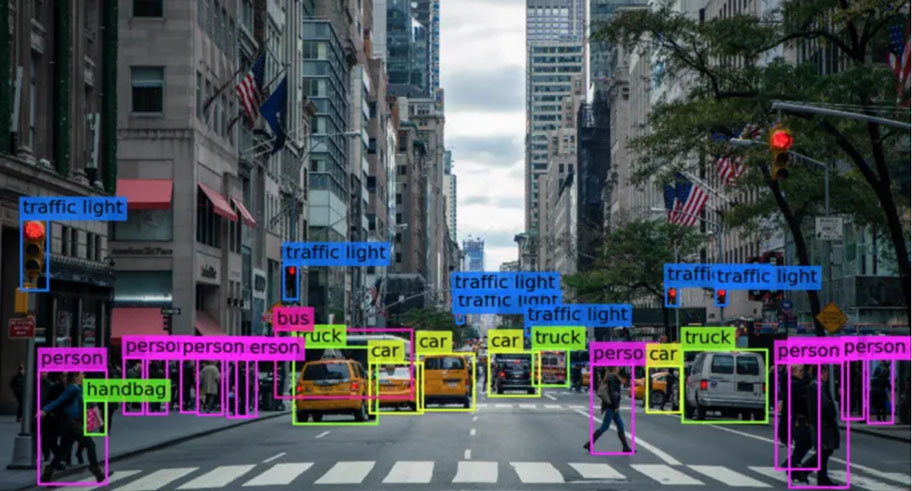
Rigorous evaluation on held-out data against a real baseline, so you know what the model does on the hard cases, not the easy ones.
We take a promising method from the literature and reproduce it on your problem, then make it fast and stable enough to ship.
If the model does not beat your current approach, we say so — and say why — before you spend a quarter building on it.
02 / Stack
Branchenstandard, langweilig im besten Sinne: Werkzeuge mit Zukunft, die auch der nächste Entwickler kennt.
Modelling
PyTorch
Model development and training
Hugging Face
Pretrained models and datasets
Fine-tuning
Fine-tuning on your task and data
LoRA
Parameter-efficient adaptation with LoRA
Evaluation
Benchmarks
Task benchmarks that match your problem
Held-out sets
Held-out sets the model never trained on
Human eval
Human evaluation where it’s the only honest judge
Baselines
A real baseline every result is measured against
Production
Distillation
Distillation for a smaller, faster model
Quantisation
Quantisation to fit real hardware budgets
Serving
Serving the model behind a stable API
Monitoring
Monitoring quality and drift once it’s live
03 / Vorgehen
We agree on the metric and the baseline before training anything, so the result is a verdict you can trust — not a number chosen to look good.
Fixed seeds, versioned data and pinned configs mean a result can be rerun and gets the same answer — by us, and by your team after us.
The model is judged on data it never saw, across the hard cases too, so the score reflects real-world use rather than a flattering sample.
If the evidence says the method does not beat your baseline, we report that early — a clear no-go is a result, not a failure.
04 / Standards
Wir halten uns bei jedem Projekt an Branchenstandards und bewährte Methoden – sie sorgen dafür, dass der Kostenvoranschlag hält.
05 / Infrastruktur
Start
Tell us the problem and what “better” would mean for you. A senior engineer — not a sales rep — writes back.
Let’s manage Proof of concept