LLMOps, evals & guardrails
Evals, tracing, guardrails and cost control — the operations layer for LLM applications.
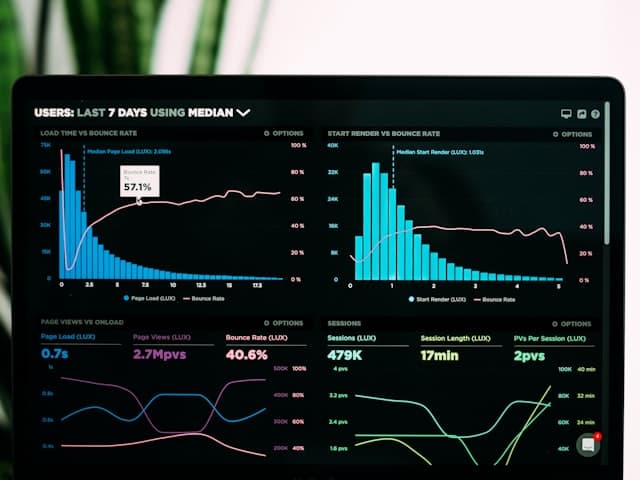
Shipping an AI feature is the easy part; keeping it accurate, safe and affordable as prompts, models and data change is the work. We set up the operations layer around your LLM applications: eval suites and LLM-as-a-judge that score every release, tracing that shows what the model saw and did, guardrails that catch unsafe input and output, and cost and latency control with model routing — so quality is measured, not assumed.
01 / What it solves
Golden datasets and judges that score accuracy, groundedness, tone and policy, so a prompt tweak or model swap can’t silently regress.
Traces of prompts, retrievals, tool calls and responses, linked to users and versions, for fast debugging.
Checks for prompt injection, data leakage, off-topic and unsafe content on input and output.
Cost per request and per feature, caching and routing to smaller models where quality allows.
02 / Stack
Industry-standard, boring in the good way: tools with a future, that the next engineer will know too.
Tracing & observability
Langfuse
Open-source LLM tracing and analytics
OpenTelemetry
Vendor-neutral telemetry standard
MLflow
Experiment tracking and evaluation
Arize Phoenix
Open-source LLM observability
Evaluation
LLM-as-a-judge
Model-graded scoring against clear criteria
Golden datasets
Curated test sets from real traffic
Promptfoo
Prompt and regression testing in CI
Ragas
Metrics for retrieval and RAG quality
Guardrails & control
Guardrail models
Input and output safety checks
LLM gateway
One entry point for routing, limits and keys
Prompt registry
Versioned prompts with rollbacks
Semantic caching
Reuse answers to repeated questions
03 / Approach
We agree with you what a good answer is and turn it into criteria and test cases before tuning anything.
Every change to prompts, models or data runs the suite; regressions block the release like a failing test.
Routing sends simple requests to small, cheap models and hard ones to the strongest, with fallbacks.
Live scoring of sampled traffic and alerts when quality, cost or latency moves.
04 / Standards
We adhere to industry standards and proven methods on every project — they are what makes the estimate hold.
05 / Infrastructure
Good questions
Straight answers to what buyers ask before they start.
Because their behaviour changes when you edit a prompt, swap a model or update your data, and nothing in a normal test suite notices. Evals turn “it seems fine” into measured quality — accuracy, groundedness, tone, policy — checked before every release.
Related work
Projects and products of ours that involved this service.
Start
Tell us which AI features you run. A senior engineer writes back with an honest scope and price.
Let’s manage See performance analytics