WNC LogoWNC
ServicesSolutionsCompanyAcademyLabsContact
Open Kanban

We No Code. We Architect.

Start a project daniel@we-nocode.com
WNC LogoWNC

AI & automation partner. Made with care across the US, Poland, Estonia, Brazil & Ukraine.

daniel@we-nocode.com+38 (068) 758-94-22+38 (095) 411-95-37
Remote-first, worldwide

Solutions

  • Atflow
  • Alt Auth
  • AdCrier
  • Pastukh
  • Olymp Hill

Portals

  • Client Portal
  • Investor Portal
  • Partner Portal

Company

  • About Us
  • Our Team
  • Case Studies
  • Testimonials
  • Investment
  • Blog
  • News
  • Careers
  • Locations
  • Contact

Labs

  • Miltech
  • AI Labs
  • Internet of Things
  • Robotics

Initiatives

  • Startup Program
  • Academy
  • Olymp Hill

Services

All services
AI
  • Agentic AI systems
  • AI agents & copilots
  • MCP servers
  • RAG pipelines
  • Voice AI agents
  • AI-native software
  • Workflow automation
  • LLMOps & evals
  • Fine-tuning & models
  • Document AI
  • Computer vision
Development
  • Web development
  • Mobile development
  • SaaS & MVP development
  • UI/UX & product design
  • Integrations & APIs
  • E-commerce development
  • Legacy modernisation
  • QA & test automation
  • No-code & low-code
  • Desktop development
Embedded & IoT
  • IoT solutions
  • Embedded firmware
  • Embedded Linux & SoC
  • Edge AI & TinyML
  • Wireless & connectivity
  • Hardware prototyping
  • IoT platform & cloud
  • Fleet & OTA management
  • Industrial IoT (IIoT)
  • IoT security
Cloud & data
  • Data engineering
  • AI cloud infrastructure
  • Server development
  • DevOps & platforms
  • Cloud migration & FinOps
  • BI & dashboards
  • Performance analytics
  • Support & SRE
Security
  • Pentesting
  • AI red teaming
  • Compliance readiness
  • Auth & identity
  • Cloud security
  • Secure SDLC
  • Supply-chain security
  • Security audits
  • Security monitoring
  • Zero trust
  • Privacy & GDPR
Advisory
  • Consulting & advisory
  • CTO-as-a-service
  • AI strategy & governance
  • Technical due diligence
  • Dedicated team
  • AI training for companies
R&D / innovation
  • Proof of concept & feasibility
  • Rapid prototyping
  • Applied AI research
  • Technology discovery & scouting

© 2026 WNC. All rights reserved.

🇺🇦Stand with Ukraine

We No Code

All services

Edge AI & TinyML

Your product sees, hears and decides on its own.

Instant responses, no cloud bill, and data that never leaves the device.

When a product has to react the moment something happens, a round trip to the cloud is too slow, too costly and stops working the instant the connection drops. We put the model on the device itself, so it responds in milliseconds, keeps working offline and never has to send the data it reads out of the customer’s hands. These are the models from our AI Labs, made to fit a microcontroller, a Jetson or the NPU in your SoC.
Let’s manage Open Kanban
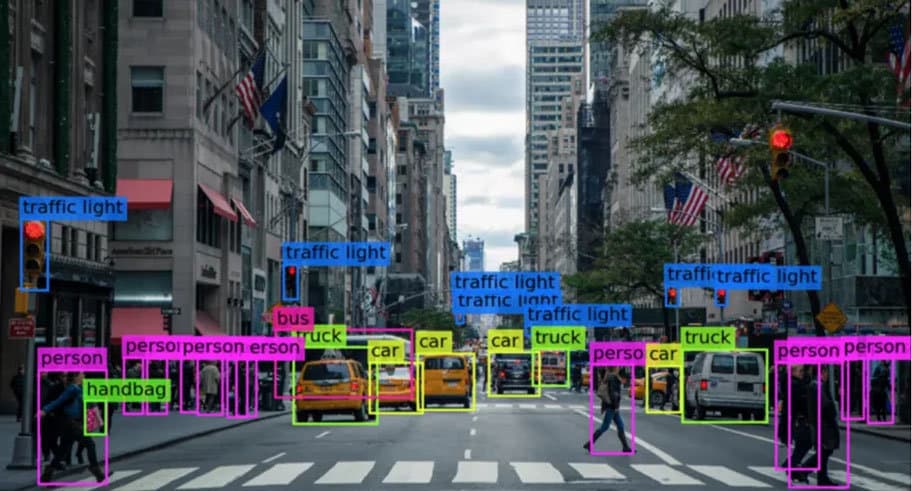
Computer vision running on an edge device

01 / What it solves

Products that react on their own.

01

See and act in real time

Spot, count and track what matters in the camera feed instantly, from a tiny Cortex-M sensor to a multi-camera Jetson rig.

02

Respond to voice, hands-free

Wake words, spoken commands and sound alerts handled on the device, with no audio sent anywhere.

03

Catch problems before they cost you

Predictive maintenance, gesture and activity recognition read straight from the sensors on board.

04

Keeps getting better after it ships

One loop from data to training to on-device evals and over-the-air updates, so the product improves in the field.

02 / Stack

The technology we build with.

Industry-standard, boring in the good way: tools with a future, that the next engineer will know too.

Inference runtimes

  • TensorFlow Lite / LiteRT

    Quantised models on MCUs and mobile SoCs

  • ONNX Runtime

    Portable inference across CPUs, GPUs and NPUs

  • TensorRT & DeepStream

    GPU-accelerated vision pipelines on Jetson

  • Edge Impulse & TinyML

    Rapid model iteration for constrained targets

Target hardware

  • Cortex-M with CMSIS-NN

    Keyword spotting and anomaly detection in kilobytes

  • NVIDIA Jetson

    Multi-camera vision at the edge

  • Google Coral / Hailo

    Dedicated accelerators for low-watt inference

  • Qualcomm & NXP NPUs

    On-SoC acceleration in production devices

Model pipeline

  • PyTorch

    Training, distillation and export

  • Quantisation & pruning

    INT8 / INT4 models that keep their accuracy

  • Evals on-device

    Accuracy, latency and power measured on the target

  • OTA model delivery

    Models shipped and rolled back like firmware

03 / Approach

How we build things that last.

01

Measured on the target

Latency, memory and current draw are measured on the real device, every model revision.

02

Milliwatts, not watts

Duty-cycled inference and accelerators chosen for the power budget the product actually has.

03

Private by design

Raw data stays on the device. Only what the product needs leaves it, if anything does.

04

One pipeline, device to cloud

Data from the fleet feeds training; a better model ships back as an ordinary update.

04 / Standards

Best practices we don’t skip.

We adhere to industry standards and proven methods on every project — they are what makes the estimate hold.

  • Start with the smallest model that could work: distilled or quantised small models before large ones
  • Quantisation-aware training before post-training tricks
  • Accuracy evals on real device captures, not the lab set
  • Latency and power budgets fixed as acceptance criteria
  • Fallback behaviour defined for low-confidence outputs
  • Model versioning and rollback through the OTA channel
  • Drift monitoring from fleet telemetry, with retraining shipped over the OTA channel
  • Privacy review of every signal that leaves the device

05 / Infrastructure

Where it runs, and how it stays up.

  • On-device benchmarking rigs (latency, memory, power)
  • Training pipeline fed by fleet data
  • OTA model delivery with rollback
  • Drift and accuracy monitoring in production

Good questions

What clients ask us

Straight answers to what buyers ask before they start.

Yes, where the hardware allows. WNC starts with the smallest model that does the job (distilled or quantised small models) and deploys it on NVIDIA Jetson and similar NPUs, with latency and power budgets as acceptance criteria.

Related work

Where we’ve done this

Projects and products of ours that involved this service.

Hirske Dzherelo
IoT · Manufacturing

Hirske Dzherelo

IoT for a factory that builds drinking-water vending machines: every machine reports to the server every 3–5 seconds and is monitored and tuned remotely from a web cabinet and a Telegram bot.

IoT · TelecomIoT service intelligence platform for mobile operators
IoT · Telecom

IoT service intelligence platform for mobile operators

From connectivity to intelligence: a platform that sits above an operator’s existing systems and turns fragmented SIM, device, traffic and service data into enterprise-facing visibility, trust and action.

Start

Want the model on the device?

Tell us what it has to see, hear or predict, and on what hardware. An engineer writes back with an honest scope and price.

Let’s manage or explore AI Labs